$ cat ~/projects/movie-review-model.md
Movie Review Model
IMDb data pipeline, analytics and machine learning.
status: Completedyear: Project
$ cat problem.md
Large-scale movie review data requires collection, cleaning, structured storage and analysis before meaningful insights or predictive models can be produced.
$ cat solution.md
Scraped and stored more than 5,000 IMDb movie records using BeautifulSoup and SQL, cleansed the dataset with Python data-processing libraries, built Tableau dashboards and trained a RandomForest regression model.
$ cat architecture.md
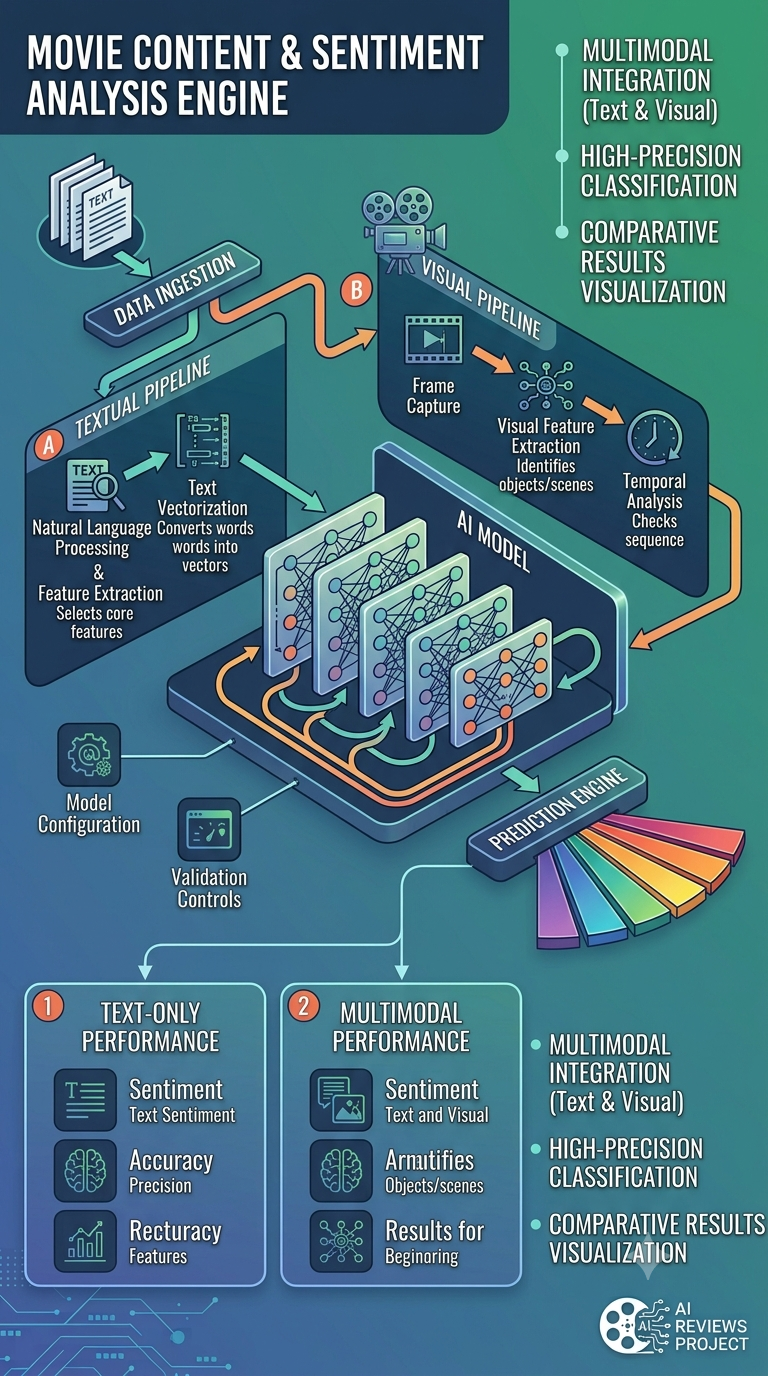
IMDb data is collected using BeautifulSoup, stored using SQL, cleaned and transformed with Python, NumPy and Pandas, visualized in Tableau, and passed into a Scikit-Learn RandomForest regression model for prediction.
$ cat responsibilities.md
- Scraped 5,000+ IMDb movie records using BeautifulSoup.
- Stored and queried movie data using SQL.
- Cleaned and transformed datasets using Python, NumPy and Pandas.
- Built Tableau dashboards for data analysis and visualization.
- Trained a RandomForest regression model using Scikit-Learn.
$ cat stack.txt
- Python
- BeautifulSoup
- SQL
- NumPy
- Pandas
- Tableau
- Scikit-Learn
- RandomForest
$ cat results.md
- Processed more than 5,000 IMDb movie records.
- Improved insights quality by approximately 40% through data cleansing and visualization.
- Achieved 96% prediction accuracy with the RandomForest regression model.
$ ls screenshots/